Blog
How to check whether Google sees the content your customers see
Compare delivered HTML, rendered content and indexed evidence before turning a JavaScript concern into a website rebuild.
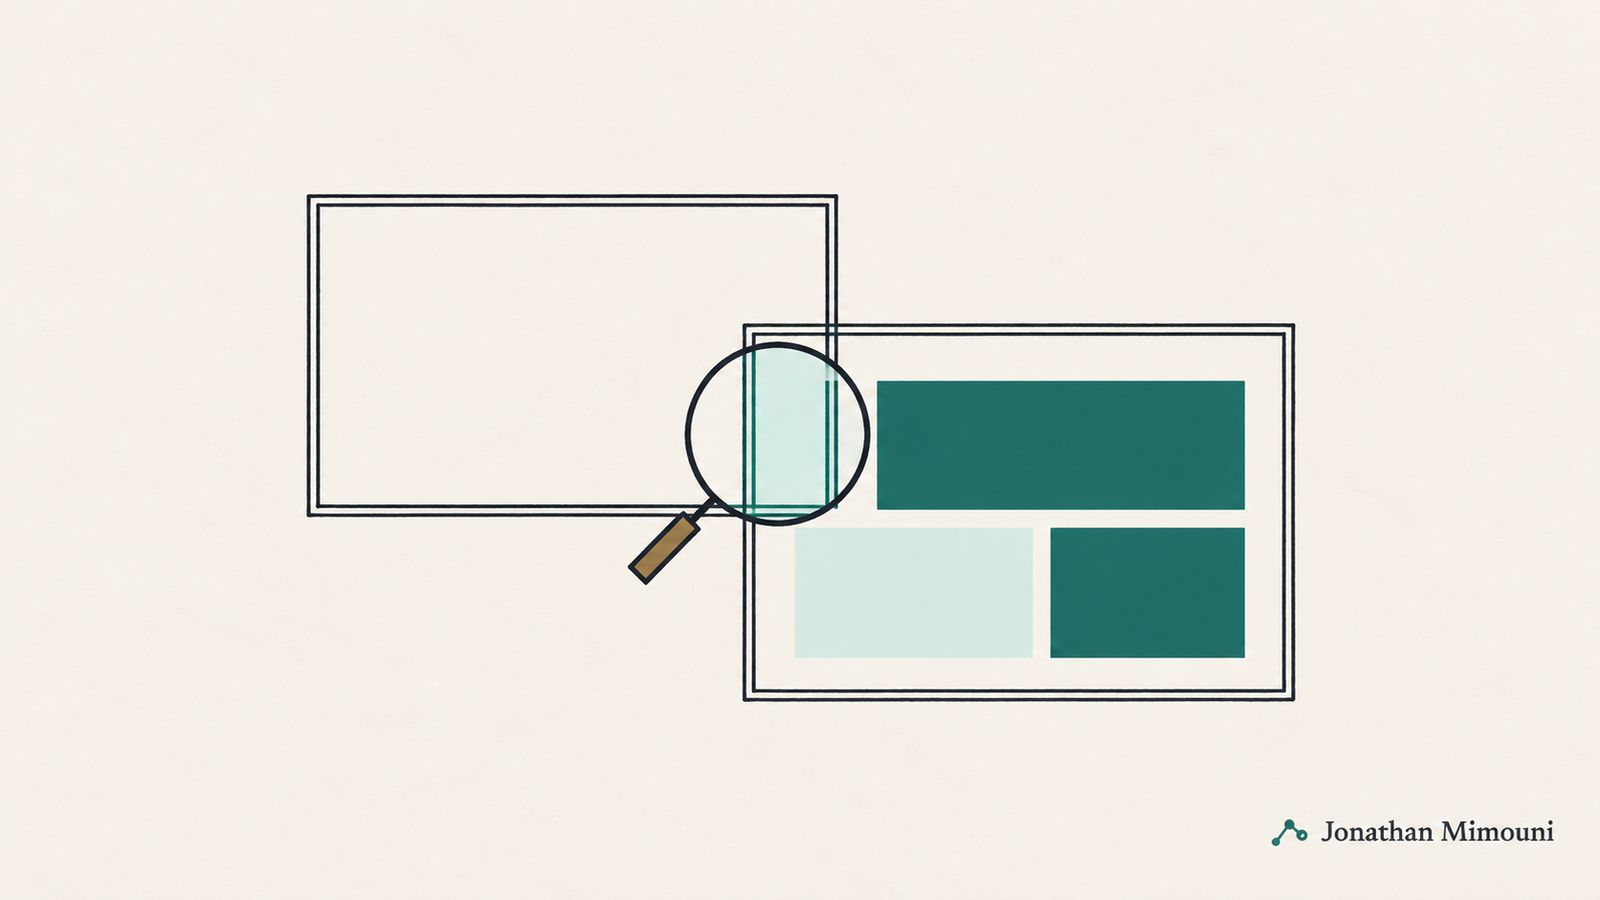
A page can look complete in your browser while an important part of its content is missing from the evidence available to Google. I would investigate that difference before recommending a different framework, server-side rendering or a rebuild.
The first useful deliverable is a precise statement of what is missing, from which version of the page, and why it matters to a customer.
Choose the content that matters
“Google cannot read our website” is a poor starting ticket. It combines an assumed cause with a conclusion about every page.
I would select an important URL and identify its essential content: perhaps the service description, product specifications, location details or links to related products. Then I would choose another URL using the same template and one that behaves differently. These comparisons help distinguish a single record problem from a shared component problem.
The business purpose should be explicit. If a product name appears but its compatibility information is missing, the page is not empty. It may still fail to answer the question that makes it useful. Conversely, a missing decorative animation is unlikely to justify the same investigation as an absent service description.
This initial selection belongs with marketing and the people responsible for the offering. Developers should receive an agreed description of the expected page, rather than having to infer its commercial priorities from a screenshot.
Understand the three views you are comparing
The server sends an initial HTML response. JavaScript can then add or change content in the browser. Google also processes pages through crawling, rendering and indexing, as its JavaScript documentation explains.
These stages create different things to inspect. Viewing page source helps reveal the initial HTML. The browser's rendered page shows the result after scripts have run in that browser. Search Console provides evidence about Google's indexed record and a separate live test.
An empty-looking source file does not prove that Google cannot index the content. It may indicate that the site depends on JavaScript to populate the page. Equally, a complete browser view does not prove that a crawler received the same resources or successfully reached the same result.
I would keep each observation labeled. A screenshot from a customer session, source HTML and inspection output are complementary evidence. Treating them as interchangeable makes the diagnosis less reliable.
Begin with the indexed record, then test the present page
For a property your team can access, inspect the exact URL in Search Console. Record its reported indexing state, crawl information and selected canonical where available. Check whether the record predates a relevant website change.
Then run a live test to examine the current page. Google states that the live test cannot predict its selected canonical and does not guarantee indexing. A successful result establishes something useful about that test, but it does not prove that the indexed record already contains the repair.
Where available, inspect the returned HTML and resource information. Search for a distinctive phrase from the important content, rather than relying entirely on appearance. Use the successful live test's screenshot as another view of the result.
Suppose the current test contains the full service explanation while the stored record reflects an earlier version. That suggests a different next action from a live test that still lacks the explanation. One concerns processing an updated page; the other requires investigating the page being delivered now.
Use a plain browser check for a narrower question
A logged-out browser visit can reveal assumptions hidden by your normal working session. The page might rely on saved preferences, a previous navigation step or an authenticated request.
Open the URL directly. Note whether the main content appears without selecting a region, clicking a button or navigating from another page. If a customer must make a choice first, record that behavior without assuming how every crawler handles it.
Disabling JavaScript can show what remains without script execution. I would use it to understand dependency, not as a simulation of Google. Google can execute JavaScript, and a browser with scripts disabled answers a different question.
Likewise, a developer console error is a clue rather than automatic proof of an indexing problem. Connect the error to the missing element. A failed analytics request and a failed product-data request may look equally alarming in a list while having very different consequences for the page.
Check access and instructions before changing architecture
Ask the technical team to investigate whether the resources needed for the missing content can be fetched. A blocked script, failed data request or infrastructure restriction can explain a discrepancy without condemning the entire application.
The page's HTTP response and indexing instructions also deserve attention. A product page that displays an error while returning a success response presents a different problem from one that delivers the correct product. A noindex instruction may be intentional on one template and accidental on another.
Google specifically warns that an initial noindex can lead it to skip rendering, making a later JavaScript removal unreliable. Conflicting canonical declarations also need investigation. These are implementation details with concrete evidence, not reasons to declare JavaScript unsuitable for search.
I would keep the technical request bounded: identify the relevant response, resource or instruction; show the observed mismatch; and ask the developer to establish its cause and scope.
Write a ticket that can be closed with evidence
A useful handoff contains a small set of verifiable items:
- The affected URL and another example using the same template.
- The exact content or link expected to appear.
- The customer view and the inspection view, clearly labeled.
- The test context and any relevant deployment change.
- The observed failure, with assumptions kept separate.
- The condition that would demonstrate a successful repair.
For a hypothetical product template, the acceptance condition might be that the specification text is present in the live rendered output and remains visible to customers. Subsequent indexing checks are a separate follow-up, not something development can promise to complete immediately.
This structure also allows a developer to challenge the initial theory. If the evidence points to an access restriction rather than rendering, the ticket should follow that evidence.
Escalate the solution only when the problem warrants it
Server-side delivery can be a sensible architectural choice, but it carries costs and dependencies. I would evaluate it against the actual reliability problem, affected templates, other crawlers and the site's broader requirements.
Sometimes the right answer is a small correction. Sometimes repeated failures across essential content justify a larger change. The evidence should make that distinction possible.
A marketing team does not need to prescribe the rendering architecture to lead this work well. It needs to define the content customers require, show where that content goes missing and insist on a repair that can be demonstrated.
Message me on WhatsApp if you need help turning a JavaScript indexing concern into a clear technical brief.
Talk to JonathanRelated posts
The Decisions I Would Settle Before Approving a Website Migration
A migration needs agreed destinations, release criteria and responsibility for what happens after the launch.
When several pages rank for the same query, which ones should you change?
Shared queries can reveal confused page roles, but they can also reflect different needs. Diagnose the difference before removing content.